Engineering · October 2, 2026 · 8 min read · 1 views
How We Put AI Split Image Layers Back Where They Belong
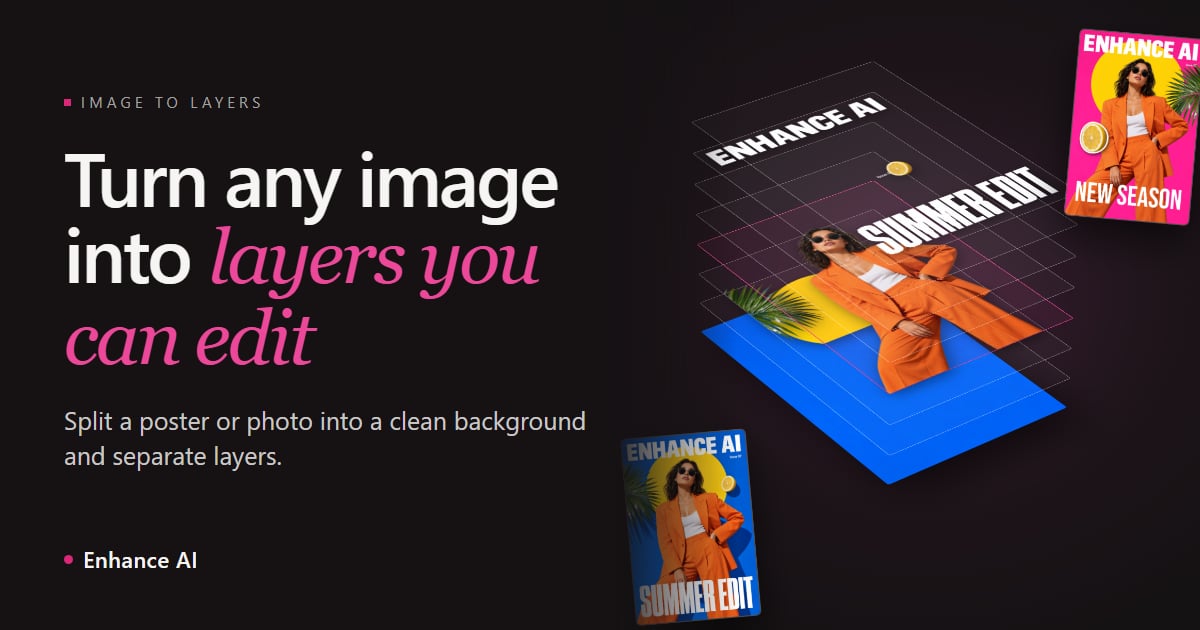
An AI model splits a picture into layers but never says where each one goes. This is how we find each layer's spot, size and stacking order.
Image to Layers turns one flat picture into a clean background plus up to 16 editable layers. An AI model does the split. Putting each piece back where it belongs is our own JavaScript on the server, and the matching itself uses no libraries, down to its own FFT.
The problem: layers with no address
The split comes from Seedream 5.0 Flash layer decomposition. Its documentation only promises a base image and up to 16 transparent layers. In our runs, one output is the clean background, fully opaque, with the space behind objects filled in; every other output is one object, cropped to itself, enlarged by its own factor (2x to 5x on a poster, more for small things) and redrawn rather than cut out.
Nothing says where a layer goes. We must find each one's position, size and place in the stack.
Why naive matching fails
Version 1 assumed layers came back at canvas scale, version 2 also searched for size, and the current version 3 matches structure. Plain template matching breaks here:
- Position and scale are both unknown, and every layer has its own scale.
- Redrawn pieces do not match pixel for pixel.
- Layers are amodal, drawn whole even where the original hides part of them, so a plain overlap score would shrink them.
- Two similar lines of text fit the same spot equally well.
- A one colour disc also matches at any smaller size inside its own region.
- Pieces can run off the canvas.
- Where layers overlap, only the original knows which is in front.
The approach, step by step
1. Read the outputs. Each output is decoded to RGBA. Empty ones (no pixel above alpha 16) are dropped. An output counts as opaque when at least 99.9 percent of its pixels have alpha 250 or more. If several are opaque, any that is just the source picture again (a mean channel difference under 3 at one eighth size) is dropped, and the largest opaque one left becomes the background and sets the canvas size. The rest are cropped to their visible pixels.
2. Build two signals by comparing the source picture with the clean background. An edge in the source that is also a change against the background belongs to an object, so background texture and the filled in area drop out.
// gradSource, gradDiff: gradient magnitudes of the source and of source minus background
function edgeMap(gradSource, gradDiff) {
  const F = new Float32Array(gradSource.length);
  for (let i = 0; i < F.length; i++) F[i] = Math.min(gradSource[i], gradDiff[i]);
  return F; // then one 3x3 blur
}

// Soft object mask, positive where the source is brighter
function signedMask(src, bg, i) {
  const d = [0, 1, 2].map((c) => src[i + c] - bg[i + c]);
  const sum = Math.abs(d[0]) + Math.abs(d[1]) + Math.abs(d[2]);
  // m is computed per full resolution pixel, then averaged down to each level;
  // the sign uses that level's averaged difference
  const m = Math.min(1, Math.max(0, (sum - 45) / (150 - 45)));
  return m * Math.tanh((d[0] + d[1] + d[2]) / 3 / 15);
}
The sign keeps a black silhouette from matching yellow type.
3. Score a placement. A candidate box scores the normalized cross correlation (NCC) of the layer's blurred gradients with the edge map, plus an F beta score of its alpha, signed the same way, against the mask. Photo cutouts with strong inner texture weight their inner gradients over their outline, and during refinement they score NCC only in a window around their own pixels. Beta squared is 2, so recall outweighs precision and a layer drawn whole is less likely to be shrunk (plain shapes need more, see below).
4. Search every offset with an FFT. On a coarse copy of the canvas, 128 px on its long side, we try every offset for enlargement factors (layer pixels per canvas pixel) from 6.5 down to as low as 0.9, dividing by 1.1 each step (1.2 for the remaining layers once the time guard trips). The edge map and mask go into one complex image as real and imaginary parts, and each template's gradients and alpha the same way. With G and Q the template spectra and F and M the map spectra, one inverse FFT per scale of conj(G)F + i conj(Q)M holds sum(gradients × edges) in its real part and sum(alpha × mask) in its imaginary part, for every offset. Plain shapes (see below) need a second inverse FFT per scale for their colour terms. Integral images supply the other sums. The grid is at least 1.6 times the coarse canvas, so a template can hang up to 30 percent past the left, right and top edges and 50 percent past the bottom. The 6 best distinct peaks move on.
5. Refine. Candidates are hill climbed over position and scale on finer levels, and at the very end (step 7) over a small aspect change too.
6. Explain away. The layer with the best score is accepted if that score is at least 1.15. Its footprint then damps the evidence it explains: edges lose up to 30 percent over the footprint grown by one pixel, and the mask up to 80 percent over the footprint. The rest are rescored and the loop repeats. A second similar line of text now finds the first line's spot weak and moves to its own. Layers that never reach 1.15 are refined on the damped maps, and up to 3 of them get a fresh FFT search there.
7. Finish. After all searches, each layer is refined once more on the finest pyramid level, on the plain maps rather than the damped ones, and now its aspect ratio may change too, in 1 percent steps. Then, on canvases 1024 px or more on the long side, each layer is polished on a crop around it at full resolution (coarser on canvases 4096 px and up), over position and scale, with a sub pixel offset from a parabola through neighbouring scores, clamped to half a pixel of that level. A layer covering more than 400,000 px at that level is polished on a coarser one.
8. Decide and stack. A layer is found when its final score is at least 0.5 and, for a plain shape, its final leak is 0.5 or less. Any other layer starts in the middle at its own size, shrunk if needed to fit within 60 percent of the canvas each way. For order, each overlapping pair is compared with the source on its overlap. Where both are solid (alpha above 200), the one whose summed RGB difference from the source is lower by more than 12 gets a vote, and at least 8 votes with a 65 percent majority order the pair. A topological sort builds the stack bottom to top, and the model's own order settles ties and cycles.
The details that mattered
Plain shapes need a colour test. Before the 29 September fixes (a colour test for plain shapes plus changes to the search order), a mostly hidden flat sun disc and a palm leaf cut off at the edge both landed small and wrong. A brighter or darker sign cannot tell yellow from orange, so a layer that is one colour and compact (under 4.5 outline pixels per square root of area; a disc is about 3.5, type 15 or more) gets a ring just outside its outline, 4 percent of its long side wide. Source pixels on that ring that differ from the background and have its colour count as a leak: above 0.35 it costs 3 times the excess, while the share of that colour found under the layer's own pixels earns 1.5 times. A disc placed too small inside its region leaks, and a final leak above 0.5 means not found.
Same input, same answer. The code says: "Everything is deterministic unless the time guard trips." Its default budget is 5400 ms. Past 75, 85 and 90 percent of it, the full resolution polish, the fresh searches and the finishing are skipped, and if the first sweep looks set to overrun, the remaining layers are searched with a coarser 1.2 scale step. So a busy server could change the result. Placement runs once per split, behind a spinner, so the layer split job gives it a 15000 ms budget instead and stores the result.
Limitations and what we would do next
- In the code's words,
found"is not a reliable confidence", and heavily textured photo cutouts can be missed. A real confidence score would come next. - No rotation or mirror search: every piece comes back upright and unflipped.
- The search starts from enlargements of at most 6.5 times, so a piece enlarged much more than that is likely to be placed too big or missed.
- Templates sit on one background tone, which is approximate where the background colour varies a lot.
- Unplaced layers carry a placed flag of false that the editor does not show yet, and should.
- Redrawn pieces can differ from the original in fine detail.
If you want to try it, Image to Layers is at enhanceai.art/image-to-layers.

Written by Kushal
Kushal builds Enhance AI and writes the technical guides, from model merging and fine tuning workflows to prompting technique and how the platform's tools work under the hood. Every prompt in his articles is run on the platform before it is published, and the failure cases he writes about are ones he actually hit.
Related Articles
All Articles


Ready to Create with AI?
Transform your ideas into stunning visuals with Enhance AI. Image generation, video creation, upscaling, and more.